GPT-6 Astra is here, and the benchmark numbers are interesting.
· 2 min read
GPT-6 Astra is here, and the benchmark numbers are interesting.
GPT-6 Astra is here, and the benchmark numbers are interesting.
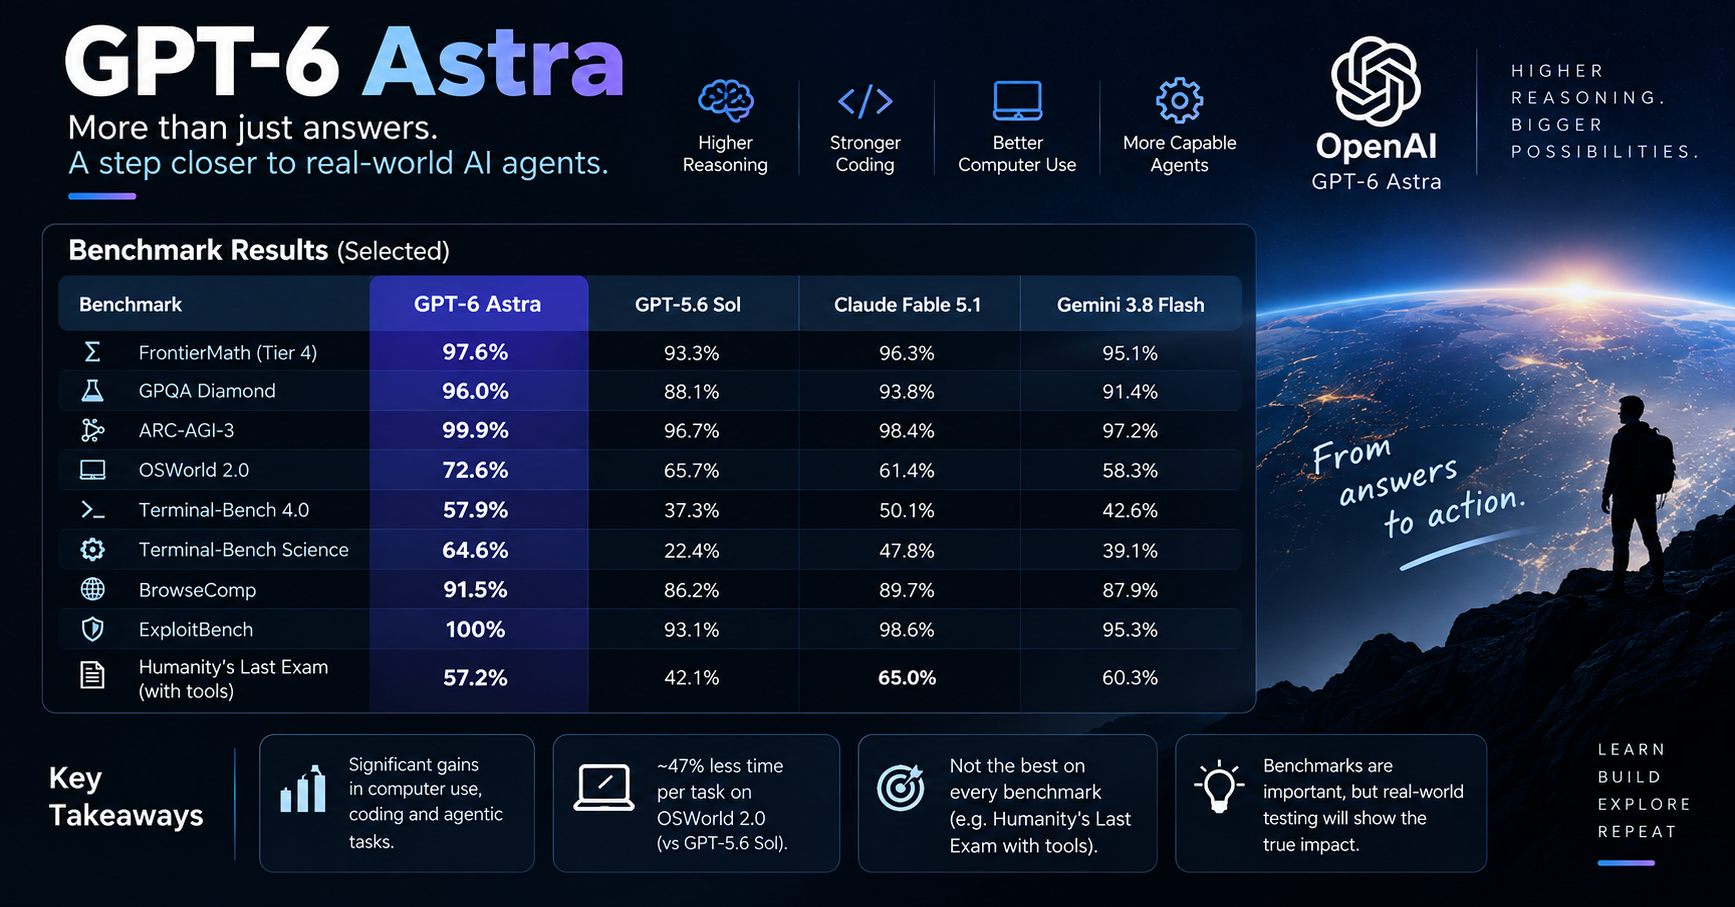
I went through the benchmarks published by OpenAI, and one thing stood out to me: Astra is not just improving on general reasoning. A lot of the gains are focused on **computer use, coding, scientific reasoning, and agentic tasks**.
Some of the numbers:
**FrontierMath Tier 4:** 97.6%
**GPQA Diamond:** 96.0%
**ARC-AGI-3:** 99.9%
**OSWorld 2.0:** 72.6%
**Terminal-Bench 4.0:** 57.9%
**Terminal-Bench Science:** 64.6%
**BrowseComp:** 91.5%
**ExploitBench:** 100%
A few comparisons are particularly interesting.
On **Terminal-Bench 4.0**, Astra scores 57.9%, compared with 37.3% for GPT-5.6 Sol.
On **Terminal-Bench Science**, the gap is even larger: 64.6% vs 22.4%.
And on **OSWorld 2.0**, Astra reaches 72.6%, compared with 65.7% for GPT-5.6 Sol, while OpenAI reports roughly 47% less time per task.
But the benchmark table also shows something important:
Astra does **not** win every benchmark.
For example, on **Humanity's Last Exam with tools**, Astra scores 57.2%, while Claude Fable 5.1 is reported at 65.0%.
That is why I find benchmark analysis more interesting than simply asking:
> “Which model has the highest score?”
Different benchmarks test very different capabilities.
A model can be extremely strong at computer use and coding while not necessarily being the best model on every reasoning or knowledge benchmark.
For me, the more interesting question is:
**How much of these benchmark improvements translate into better performance on real-world tasks?**
Especially for AI agents, I think metrics like:
* task completion rate
* number of iterations
* tool-use reliability
* latency
* token usage
* cost per completed task
may eventually matter as much as benchmark accuracy itself.
GPT-6 Astra looks like a significant step toward models that don't just answer questions, but can actually **work through multi-step tasks using computers and tools.**
Still, benchmarks are measurements—not the whole picture.
I'm interested in testing where Astra actually performs better in practice.
#ML Models